Publications
Everything we have published.
Every paper has its own page with the figure, the abstract, and links to the PDF, the publisher, the code and the dataset where they exist. Filter by keyword, person, year or type.
41papers
2026
 WACV 2026
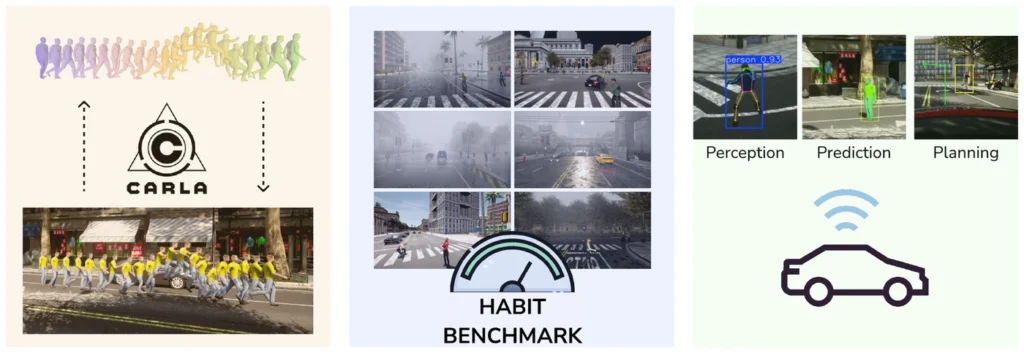
HABIT: Human action benchmark for interactive traffic in CARLA
pedestrianssimulationbenchmarkplanningmotion generation@inproceedings{Ramesh2026HABIT, title = {HABIT: Human Action Benchmark for Interactive Traffic in CARLA}, author = {Mohan Ramesh and Mark Azer and Fabian B. Flohr}, url = {https://openaccess.thecvf.com/content/WACV2026/papers/Ramesh_HABIT_Human_Action_Benchmark_for_Interactive_Traffic_in_CARLA_WACV_2026_paper.pdf}, year = {2026}, date = {2026-03-10}, urldate = {2026-01-01}, booktitle = {2026 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }- ICPR 2026
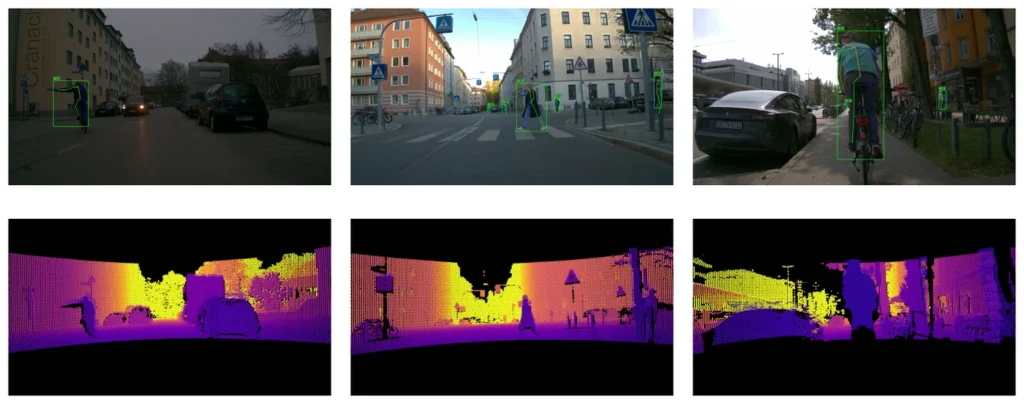
bikeActions: An action classification dataset for cyclist behaviour
cyclistsvulnerable road usersdatasetbenchmarkintent@inproceedings{Buettner2026bikeActions, title = {bikeActions: Action Classification Dataset for Behavior Understanding of Vulnerable Road Users}, author = {Max A. Buettner and Kanak Mazumder and Luca Koecher and Mario Finkbeiner and Sebastian Niebler and Fabian B. Flohr}, url = {https://arxiv.org/abs/2601.10521}, year = {2026}, date = {2026-01-01}, urldate = {2026-01-01}, booktitle = {International Conference on Pattern Recognition (ICPR)}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE ITSC
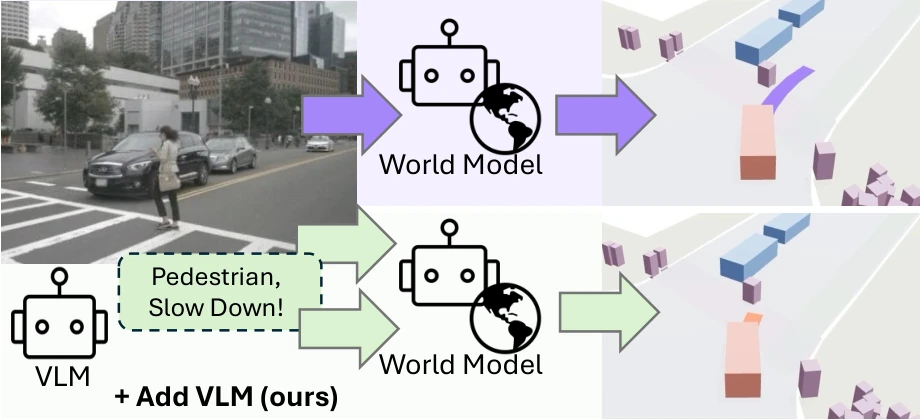
WorldVLM: Combining world model forecasting and vision-language reasoning
world modelslanguage modelsplanninggenerative modelsend-to-end driving@inproceedings{Englmeier2026WorldVLM, title = {WorldVLM: Combining World Model Forecasting and Vision-Language Reasoning}, author = {Stefan Englmeier and Katharina Winter and Fabian B. Flohr}, booktitle = {2026 IEEE International Conference on Intelligent Transportation Systems (ITSC)}, year = {2026}, note = {arXiv:2603.14497} } - ITSC 2026
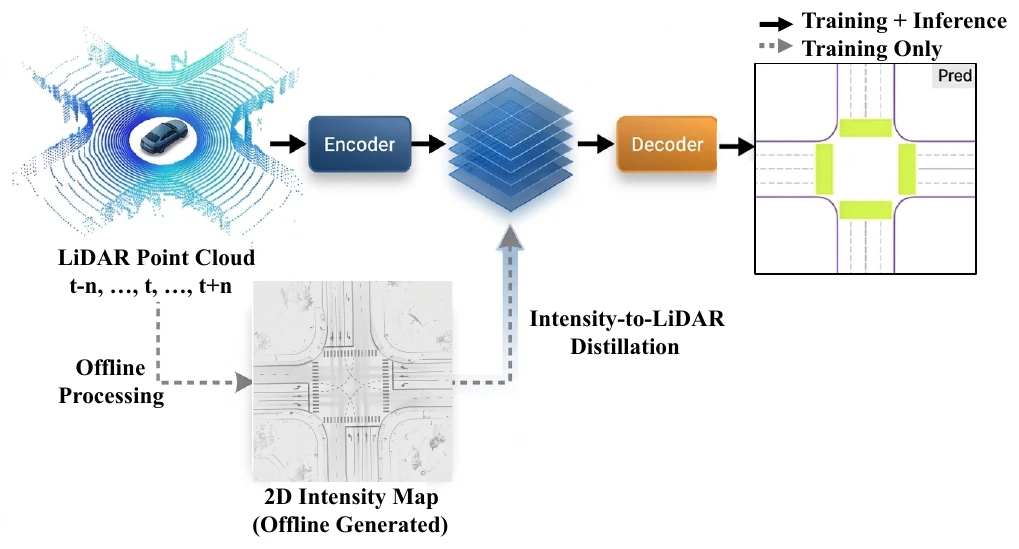
LIE: LiDAR-only HD map construction with intensity enhancement
hd mapslidarpoint cloudsknowledge distillationbev@inproceedings{Mazumder2026LIE, title = {LIE: LiDAR-only HD Map Construction with Intensity Enhancement via Online Knowledge Distillation}, author = {Kanak Mazumder and Fabian B. Flohr}, url = {https://arxiv.org/pdf/2605.01478}, year = {2026}, date = {2026-01-01}, urldate = {2026-01-01}, booktitle = {International Conference on Intelligent Transportation Systems (ITSC)}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE IV 2026
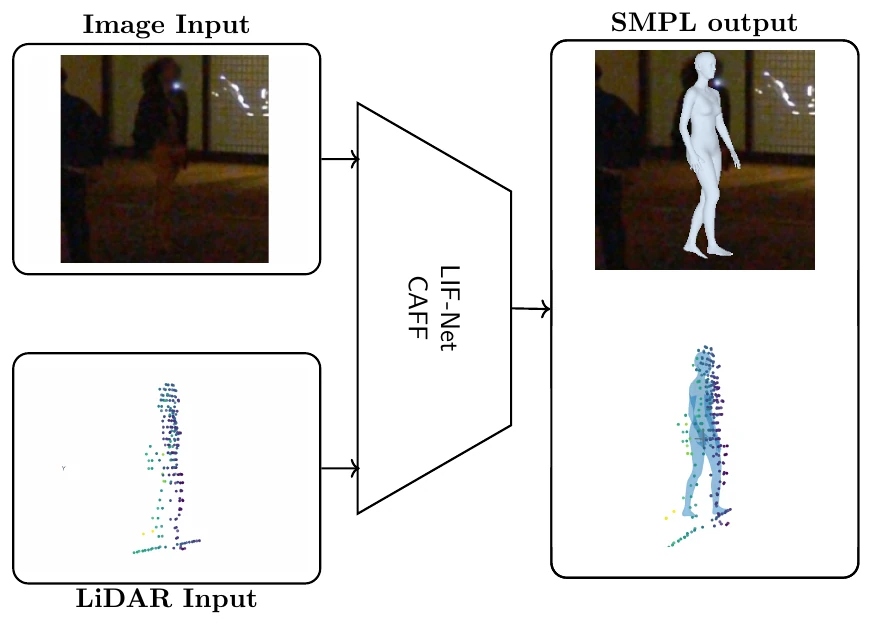
LIF-Net: LiDAR–camera fusion for 3D human pose in urban scenes
3d posesensor fusionlidarcameravulnerable road users@inproceedings{Buettner2026LIFNet, title = {LIF-Net: LiDAR-Camera Fusion for 3D Human Pose in Urban Scenes}, author = {Max A. Buettner and Erik Schuetz and Fabian B. Flohr}, url = {https://iv.ee.hm.edu/wp-content/uploads/2026/01/iv2025_buettner_fused3dhps-2.pdf}, year = {2026}, date = {2026-01-01}, urldate = {2026-01-01}, booktitle = {2026 IEEE Intelligent Vehicles Symposium (IV)}, organization = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE ICRA
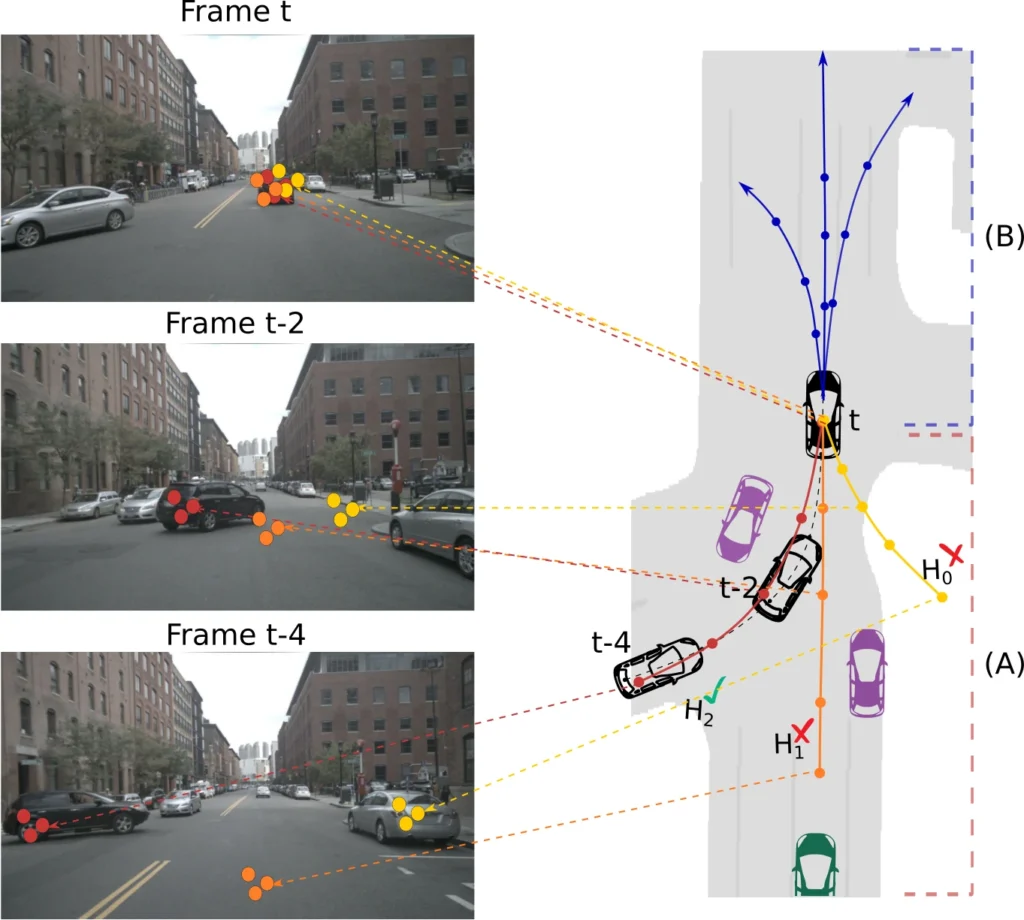
MASAR: Motion-appearance synergy refinement for joint detection and trajectory forecasting
trajectory prediction3D object detectionend-to-end drivingtransformersnuScenes@inproceedings{BencheikhLehocine2026MASAR, title = {{MASAR}: Motion-Appearance Synergy Refinement for Joint Detection and Trajectory Forecasting}, author = {Bencheikh Lehocine, Mohammed Amine and Schmidt, Julian and Moosmann, Frank and Gupta, Dikshant and Flohr, Fabian B.}, booktitle = {2026 IEEE International Conference on Robotics and Automation (ICRA)}, year = {2026}, note = {arXiv:2602.13003} } - ICPR 2026
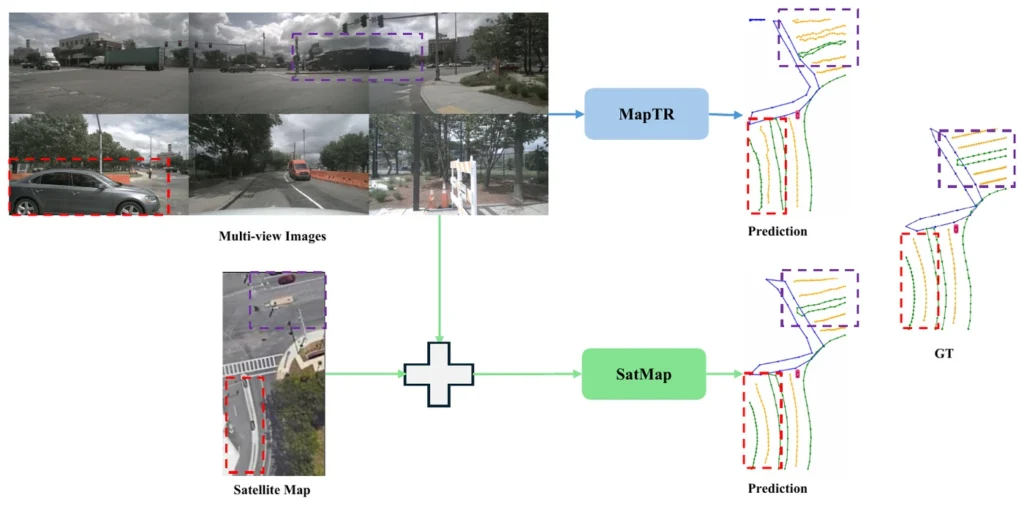
SatMap: Satellite maps as a prior for online HD map construction
hd mapscamerasensor fusionsatellite imagerybev@inproceedings{Mazumder2026SatMap, title = {SatMap: Revisiting Satellite Maps as Prior for Online HD Map Construction}, author = {Kanak Mazumder and Fabian B. Flohr}, url = {https://arxiv.org/abs/2601.10512}, year = {2026}, date = {2026-01-01}, urldate = {2026-01-01}, booktitle = {International Conference on Pattern Recognition (ICPR)}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - 2026
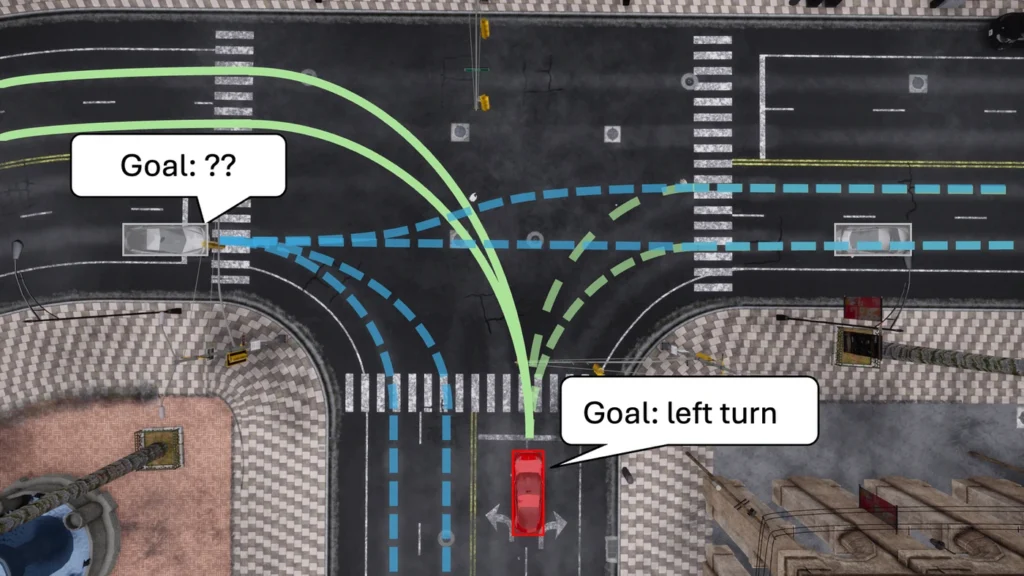
PlanTRansformer: Unified prediction and planning with a goal-conditioned transformer
trajectory predictionplanningintenttransformer@inproceedings{Selzer2026PlanTRansfor, title = {PlanTRansformer: Unified Prediction and Planning with Goal-conditioned Transformer}, author = {Constantin Selzer and Fabian B. Flohr}, url = {https://github.com/SelzerConst/PlanTRansformer}, year = {2026}, date = {2026-01-01}, booktitle = {2026 IEEE Intelligent Vehicles Symposium (IV)}, organization = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2025
- 2025
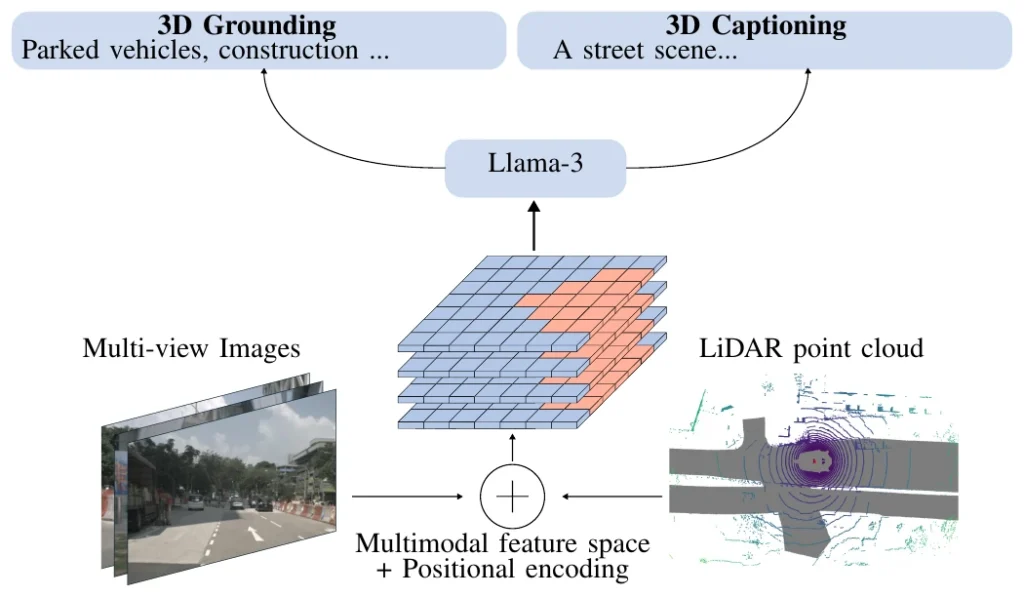
BEV-LLM: Multimodal BEV maps for scene captioning
language modelssensor fusionlidarcameradataset@inproceedings{Brandsttter2025BEVLLM, title = {BEV-LLM: Leveraging Multimodal BEV Maps for Scene Captioning in Autonomous Driving}, author = {Felix Brandstätter and Erik Schütz and Katharina Winter and Fabian B. Flohr}, url = {https://ieeexplore.ieee.org/abstract/document/11097781}, doi = {10.1109/IV64158.2025.11097781}, isbn = {979-8-3315-3803-3}, year = {2025}, date = {2025-08-06}, booktitle = {2025 IEEE Intelligent Vehicles Symposium (IV)}, pages = {345-350}, publisher = {IEEE}, abstract = {Autonomous driving technology has the potential to transform transportation, but its wide adoption depends on the development of interpretable and transparent decision-making systems. Scene captioning, which generates natural language descriptions of the driving environment, plays a crucial role in enhancing transparency, safety, and human-AI interaction. We introduce BEV-LLM, a lightweight model for 3D captioning of autonomous driving scenes. BEV-LLM leverages BEVFusion to combine 3D LiDAR point clouds and multi-view images, incorporating a novel absolute positional encoding for view-specific scene descriptions. Despite using a small 1B parameter base model, BEV-LLM achieves competitive performance on the nuCaption dataset, surpassing state-of-the-art by up to 5% in BLEU scores. Additionally, we release two new datasets — nu-View (focused on environmental conditions and viewpoints) and GroundView (focused on object grounding) — to better assess scene captioning across diverse driving scenarios and address gaps in current benchmarks, along with initial benchmarking results demonstrating their effectiveness.}, howpublished = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IROS 2025
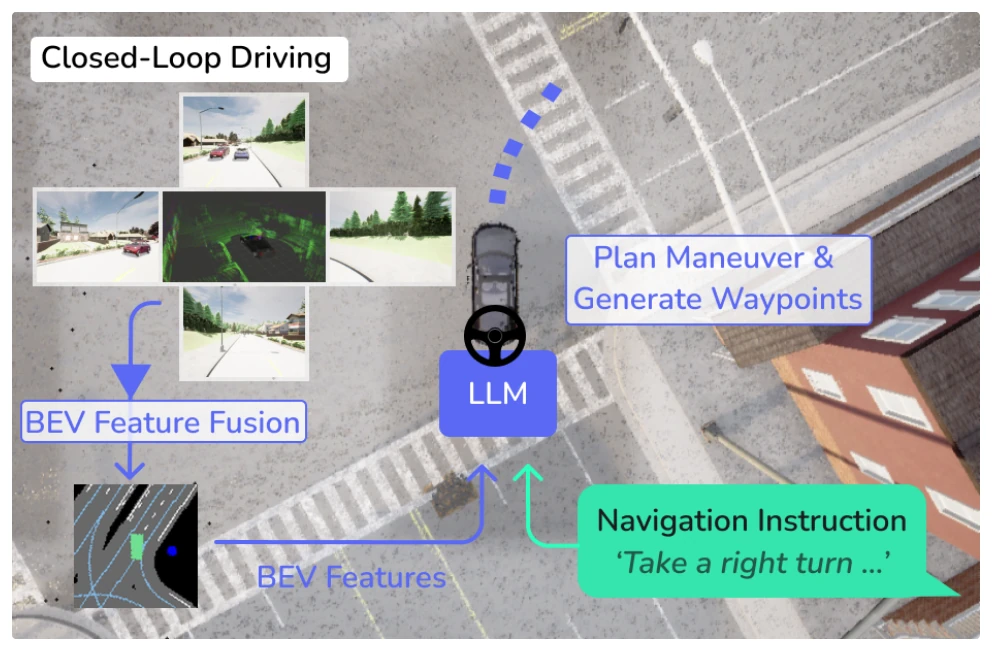
BEVDriver: BEV maps in LLMs for robust closed-loop driving
language modelsplanningsimulationsensor fusionlidar@conference{Winter2025BEVDriver, title = {BEVDriver: Leveraging BEV Maps in LLMs for Robust Closed-Loop Driving}, author = {Katharina Winter and Mark Azer and Fabian B. Flohr}, url = {https://iv.ee.hm.edu/bevdriver/ https://ieeexplore.ieee.org/document/11247237}, doi = {10.1109/IROS60139.2025.11247237}, year = {2025}, date = {2025-11-27}, booktitle = {IEEE/RSJ International Conference on Intelligent Robots and Systems}, pages = {20379-20385}, publisher = {IEEE}, abstract = {Autonomous driving has the potential to set the stage for more efficient future mobility, requiring the research domain to establish trust through safe, reliable and transparent driving. Large Language Models (LLMs) possess reasoning capabilities and natural language understanding, presenting the potential to serve as generalized decision-makers for ego-motion planning that can interact with humans and navigate environments designed for human drivers. While this research avenue is promising, current autonomous driving approaches are challenged by combining 3D spatial grounding and the reasoning and language capabilities of LLMs. We introduce BEVDriver, an LLM-based model for end-to-end closed-loop driving in CARLA that utilizes latent BEV features as perception input. BEVDriver includes a BEV encoder to efficiently process multi-view images and 3D LiDAR point clouds. Within a common latent space, the BEV features are propagated through a Q-Former to align with natural language instructions and passed to the LLM that predicts and plans precise future trajectories while considering navigation instructions and critical scenarios. On the LangAuto benchmark, our model reaches up to 18.9% higher performance on the Driving Score compared to SoTA methods.}, keywords = {}, pubstate = {published}, tppubtype = {conference} } - 2025
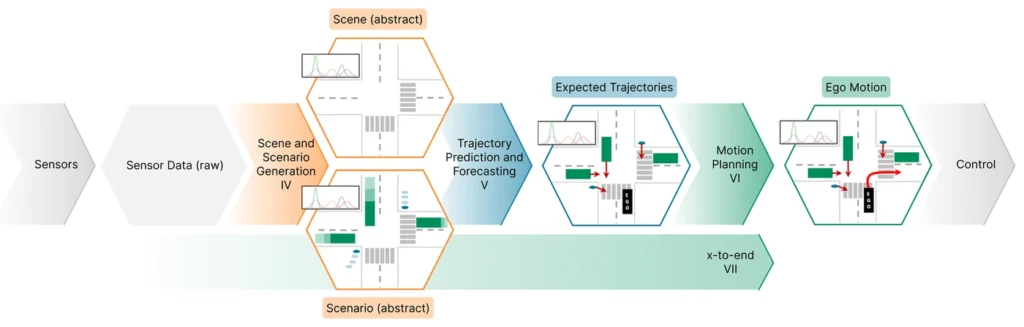
Generative AI for Autonomous Driving: A review
surveygenerative modelsworld modelsplanningsimulation@misc{Winter2025GenerativeAI, title = {Generative AI for Autonomous Driving: A Review}, author = {Katharina Winter and Abhishek Vivekanandan and Rupert Polley and Yinzhe Shen and Christian Schlauch and Mohamed-Khalil Bouzidi and Bojan Derajic and Natalie Grabowsky and Annajoyce Mariani and Dennis Rochau and Giovanni Lucente and Harsh Yadav and Firas Mualla and Adam Molin and Sebastian Bernhard and Christian Wirth and Ömer Sahin Tas and Nadja Klein and Fabian B. Flohr and Hanno Gottschalk}, url = {https://arxiv.org/abs/2505.15863}, year = {2025}, date = {2025-05-21}, urldate = {2025-05-21}, abstract = {Generative AI (GenAI) is rapidly advancing the field of Autonomous Driving (AD), extending beyond traditional applications in text, image, and video generation. We explore how generative models can enhance automotive tasks, such as static map creation, dynamic scenario generation, trajectory forecasting, and vehicle motion planning. By examining multiple generative approaches ranging from Variational Autoencoder (VAEs) over Generative Adversarial Networks (GANs) and Invertible Neural Networks (INNs) to Generative Transformers (GTs) and Diffusion Models (DMs), we highlight and compare their capabilities and limitations for AD-specific applications. Additionally, we discuss hybrid methods integrating conventional techniques with generative approaches, and emphasize their improved adaptability and robustness. We also identify relevant datasets and outline open research questions to guide future developments in GenAI. Finally, we discuss three core challenges: safety, interpretability, and realtime capabilities, and present recommendations for image generation, dynamic scenario generation, and planning.}, keywords = {}, pubstate = {forthcoming}, tppubtype = {misc} } - 2025
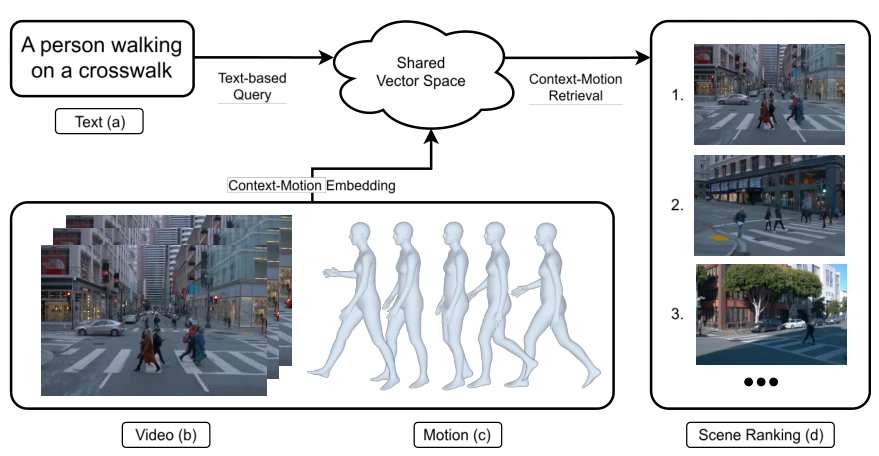
ContextMotionCLIP: Open-vocabulary motion retrieval for driving scenes
retrievalvulnerable road users3d poselanguage modelsdataset@article{Englmeier2025Contextbased, title = {Context-based Motion Retrieval using Open Vocabulary Methods for Autonomous Driving}, author = {Stefan Englmeier and Max A. Büttner and Katharina Winter and Fabian B. Flohr}, url = {https://arxiv.org/abs/2508.00589}, year = {2025}, date = {2025-01-01}, journal = {arXiv preprint arXiv:2508.00589}, keywords = {}, pubstate = {published}, tppubtype = {article} }
2024
- ITSC 2024
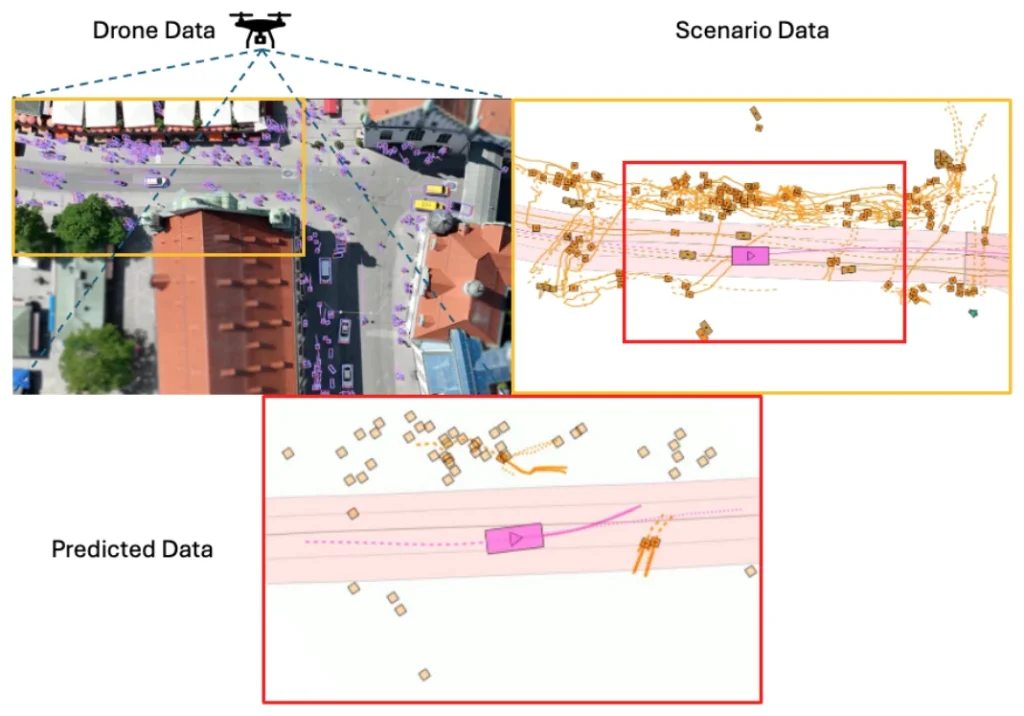
DeepUrban: Interaction-aware trajectory prediction from aerial imagery
trajectory predictionplanningdatasetbenchmarkdrones@conference{Selzer2024DeepUrban, title = {DeepUrban: Interaction-aware Trajectory Prediction and Planning for Automated Driving by Aerial Imagery}, author = {Constantin Selzer and Fabian B. Flohr}, url = {iv.ee.hm.edu/deepurban}, year = {2024}, date = {2024-07-31}, urldate = {2024-07-31}, booktitle = {IEEE International Conference on Intelligent Transportation Systems (accepted for publication)}, volume = {27}, publisher = {IEEE}, abstract = {The efficacy of autonomous driving systems hinges critically on robust prediction and planning capabilities. However, current benchmarks are impeded by a notable scarcity of scenarios featuring dense traffic, which is essential for understanding and modeling complex interactions among road users. To address this gap, we collaborated with our industrial partner, DeepScenario, to develop "DeepUrban"—a new drone dataset designed to enhance trajectory prediction and planning benchmarks focusing on dense urban settings. DeepUrban provides a rich collection of 3D traffic objects, extracted from high-resolution images captured over urban intersections at approximately 100 meters altitude. The dataset is further enriched with comprehensive map and scene information to support advanced modeling and simulation tasks. We evaluate state-of-the-art (SOTA) prediction and planning methods, and conducted experiments on generalization capabilities. Our findings demonstrate that adding DeepUrban to nuScenes can boost the accuracy of vehicle predictions and planning, achieving improvements up to 44.1% / 44.3% on the ADE / FDE metrics.}, keywords = {}, pubstate = {forthcoming}, tppubtype = {conference} } - IEEE IV 2024
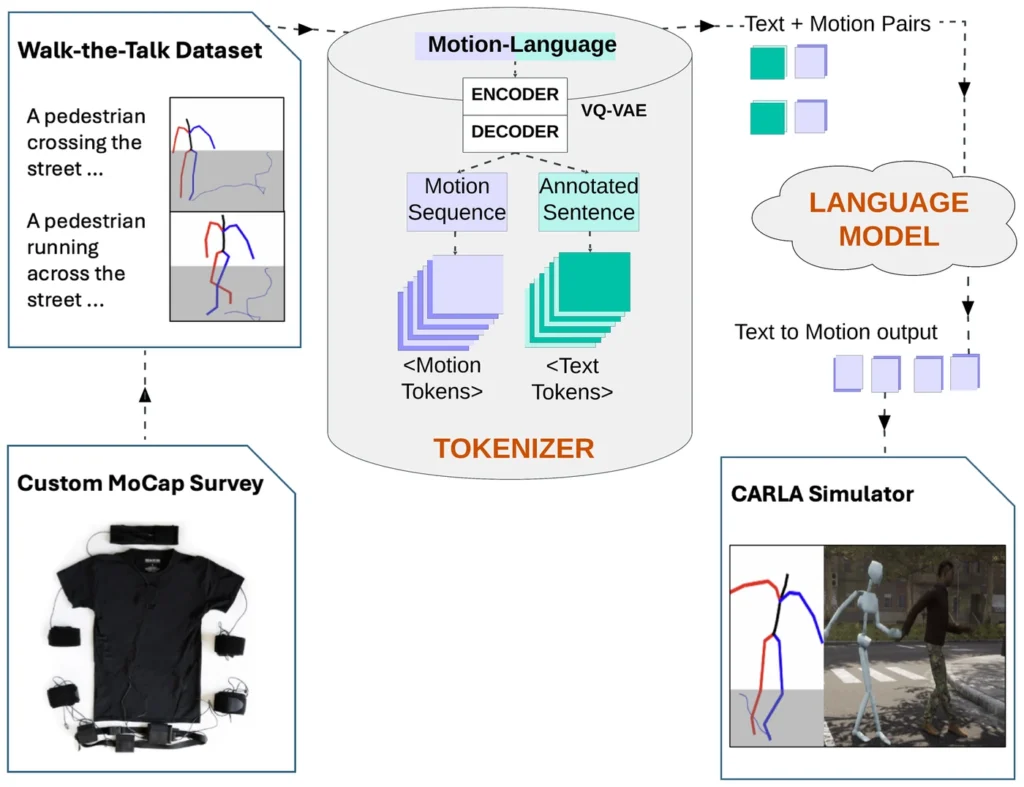
Walk-the-Talk: LLM-driven pedestrian motion generation
pedestriansmotion generationlanguage modelssimulationdataset@conference{Ramesh2024WalktheTalk, title = {Walk-the-Talk: LLM driven pedestrian motion generation}, author = {Mohan Ramesh and Fabian B. Flohr}, url = {iv.ee.hm.edu/publications/w-the-t/}, doi = {10.1109/IV55156.2024.10588860}, issn = {2642-7214}, year = {2024}, date = {2024-08-01}, urldate = {2024-08-01}, booktitle = {2024 IEEE Intelligent Vehicles Symposium (IV)}, pages = {3057-3062}, publisher = {IEEE}, address = {Jeju Island, Korea, Republic of}, abstract = {In the field of autonomous driving, a key challenge is the “reality gap”: transferring knowledge gained in simulation to real-world settings. Despite various approaches to mitigate this gap, there’s a notable absence of solutions targeting agent behavior generation which are crucial for mimicking spontaneous, erratic, and realistic actions of traffic participants. Recent advancements in Generative AI have enabled the representation of human activities in semantic space and generate real human motion from textual descriptions. Despite current limitations such as modality constraints, motion sequence length, resource demands, and data specificity, there’s an opportunity to innovate and use these techniques in the intelligent vehicles domain. We propose Walk-the-Talk, a motion generator utilizing Large Language Models (LLMs) to produce reliable pedestrian motions for high-fidelity simulators like CARLA. Thus, we contribute to autonomous driving simulations by aiming to scale realistic, diverse long-tail agent motion data – currently a gap in training datasets. We employ Motion Capture (MoCap) techniques to develop the Walk-the-Talk dataset, which illustrates a broad spectrum of pedestrian behaviors in street-crossing scenarios, ranging from standard walking patterns to extreme behaviors such as drunk walking and near-crash incidents. By utilizing this new dataset within a LLM, we facilitate the creation of realistic pedestrian motion sequences, a capability previously unattainable (cf. Figure 1). Additionally, our findings demonstrate that leveraging the Walk-the-Talk dataset enhances cross-domain generalization and significantly improves the Fréchet Inception Distance (FID) score by approximately 15% on the HumanML3D dataset.}, keywords = {}, pubstate = {published}, tppubtype = {conference} }
2023
- IEEE IV
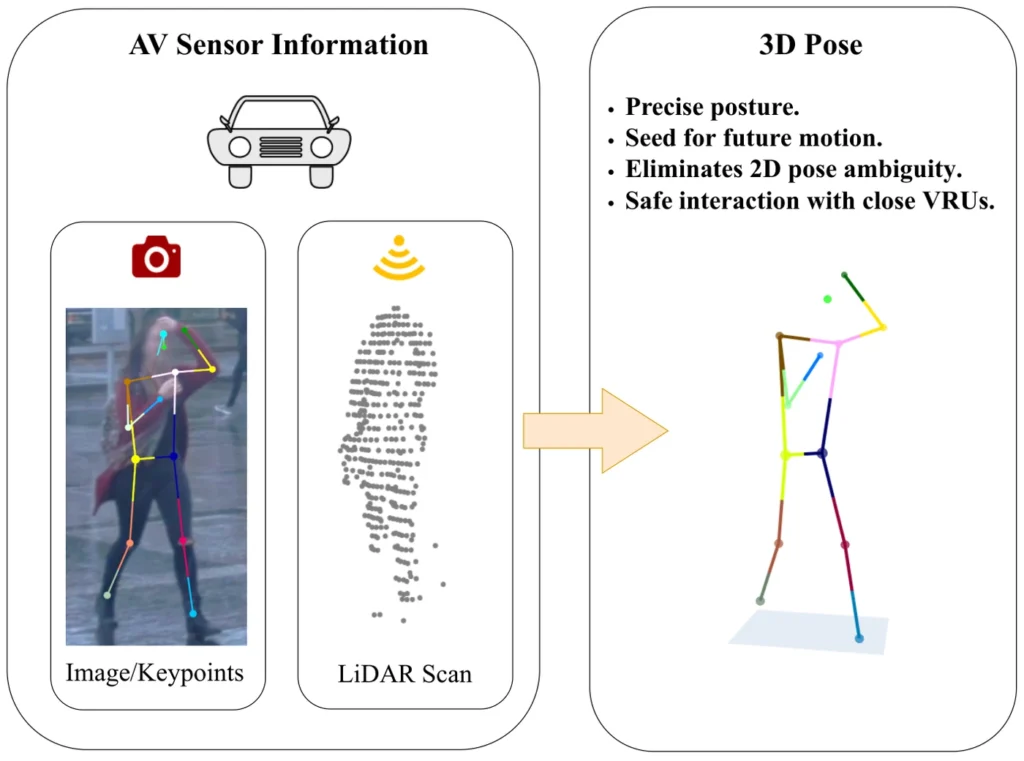
Weakly Supervised Multi-Modal 3D Human Body Pose Estimation for Autonomous Driving
3d posepedestrianssensor fusionlidarcamera@conference{Bauer2023WeaklySuperv, title = {Weakly Supervised Multi-Modal 3D Human Body Pose Estimation for Autonomous Driving}, author = {Peter Bauer and Arij Bouazizi and Ulrich Kressel and Fabian Flohr}, year = {2023}, date = {2023-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV) (accepted for publication)}, keywords = {}, pubstate = {published}, tppubtype = {conference} } - Journal article
A Review of Trajectory Prediction Methods for the Vulnerable Road User
surveytrajectory predictionvulnerable road userspedestrianscyclists@article{Schuetz2023AReviewofTra, title = {A Review of Trajectory Prediction Methods for the Vulnerable Road User}, author = {Erik Schuetz and Fabian B Flohr}, editor = {Bruno Brito and Giorgos Mamakoukas}, doi = {https://doi.org/10.3390/robotics13010001}, year = {2023}, date = {2023-12-19}, journal = {MDPI Robotics - Special Issue Motion Trajectory Prediction for Mobile Robots}, volume = {13}, number = {1}, issue = {1}, abstract = {Predicting the trajectory of other road users, especially vulnerable road users (VRUs), is an important aspect of safety and planning efficiency for autonomous vehicles. With recent advances in Deep-Learning-based approaches in this field, physics- and classical Machine-Learning-based methods cannot exhibit competitive results compared to the former. Hence, this paper provides an extensive review of recent Deep-Learning-based methods in trajectory prediction for VRUs and autonomous driving in general. We review the state and context representations and architectural insights of selected methods, divided into categories according to their primary prediction scheme. Additionally, we summarize reported results on popular datasets for all methods presented in this review. The results show that conditional variational autoencoders achieve the best overall results on both pedestrian and autonomous driving datasets. Finally, we outline possible future research directions for the field of trajectory prediction in autonomous driving.}, keywords = {}, pubstate = {published}, tppubtype = {article} } - Conference paper
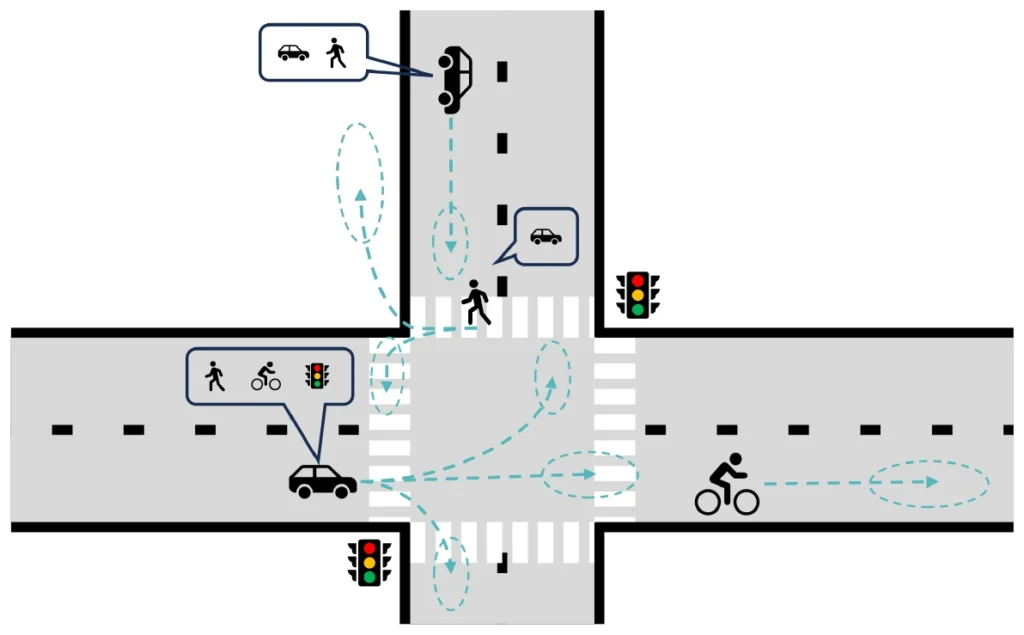
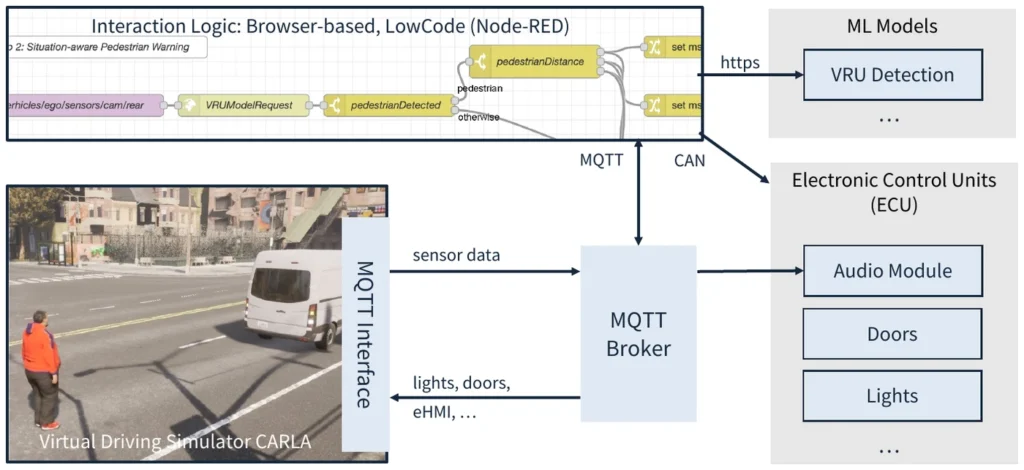
Using Node-RED as a Low-Code Approach to Model Interaction Logic of Machine-Learning-Supported EHMIs for the Virtual Driving Simulator Carla
hmivulnerable road usersdetectionsimulationlow-code@inproceedings{Winkelmann2023UsingNodeRED, title = {Using Node-RED as a Low-Code Approach to Model Interaction Logic of Machine-Learning-Supported EHMIs for the Virtual Driving Simulator Carla}, author = {Sven Winkelmann and Max Büttner and Dharani Deivasihamani and Alexander Hoffmann and Fabian Flohr}, url = {https://doi.org/10.1145/3581961.3609844}, doi = {10.1145/3581961.3609844}, isbn = {9798400701122}, year = {2023}, date = {2023-01-01}, booktitle = {Adjunct Proceedings of the 15th International Conference on Automotive User Interfaces and Interactive Vehicular Applications}, pages = {323–326}, publisher = {Association for Computing Machinery}, address = {Ingolstadt, Germany}, series = {AutomotiveUI '23 Adjunct}, abstract = {External Human-Machine Interfaces (eHMI) enable interaction between vehicles and Vulnerable Road Users (VRU), for example, to warn VRUs of the car’s presence. Warning systems should warn of the situation’s urgency, which can be achieved using Machine Learning (ML)-based VRU detection models. ML models and eHMI interaction concepts are usually developed by different teams and tested separately, often resulting in integration problems. This work contributes to a low-code approach to model interaction concepts involving ML models to enable end-to-end prototypes for early integration and User eXperience (UX) testing. We use flow-based modeling with Node-RED, the virtual driving simulator CARLA and YOLOv5 as state-of-the-art deep learning techniques for VRU detection. We show two scenarios (cornering lights and context-aware VRU warning) in an interactive demonstrator, meaning a manual live control of pedestrian and car. We consider our approach to model and evaluate interaction concepts without writing code feasible for non-computer scientists.}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2022
- Conference paper
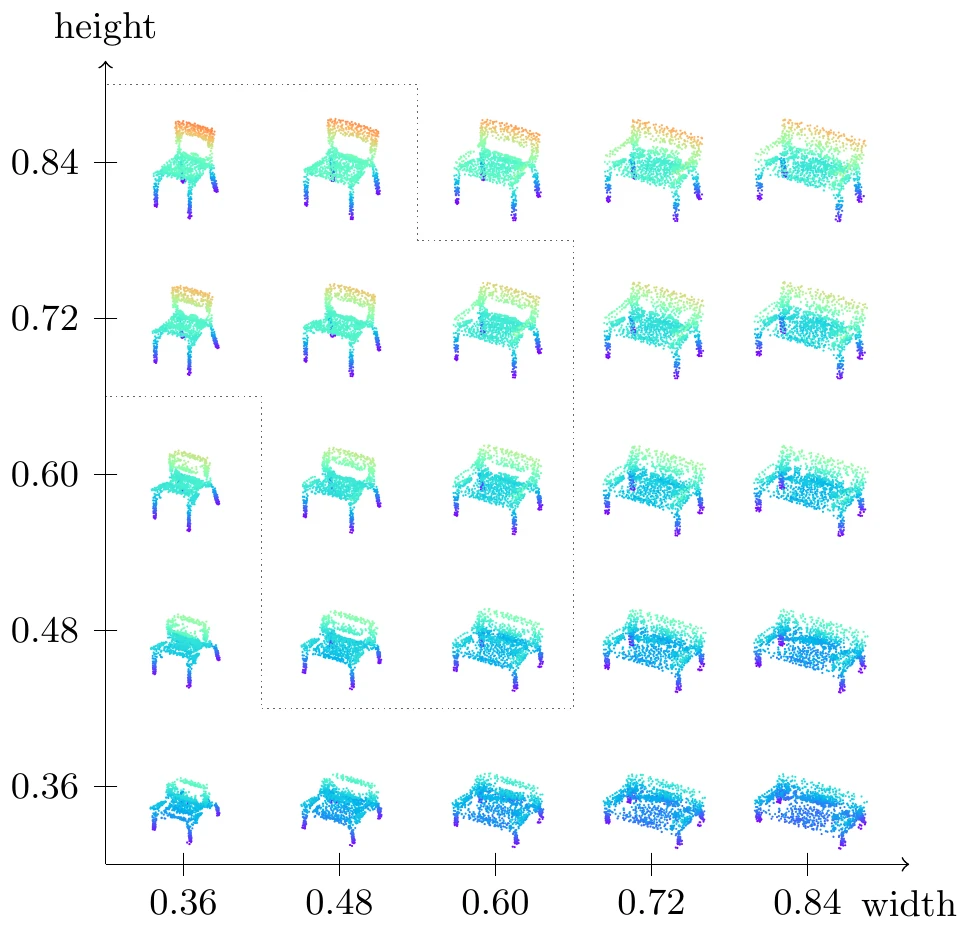
Point Cloud Generation with Continuous Conditioning
point cloudsgenerative models3d shape generation@inproceedings{Triess2022PointCloudGe, title = {Point Cloud Generation with Continuous Conditioning}, author = {Larissa T Triess and Andre Bühler and David Peter and Fabian B Flohr and Marius Zöllner}, editor = {Gustau Camps-Valls and Francisco J R Ruiz and Isabel Valera}, url = {https://proceedings.mlr.press/v151/triess22a.html}, year = {2022}, date = {2022-03-01}, booktitle = {Proceedings of The 25th International Conference on Artificial Intelligence and Statistics}, volume = {151}, pages = {4462--4481}, publisher = {PMLR}, series = {Proceedings of Machine Learning Research}, abstract = {Generative models can be used to synthesize 3D objects of high quality and diversity. However, there is typically no control over the properties of the generated object.This paper proposes a novel generative adversarial network (GAN) setup that generates 3D point cloud shapes conditioned on a continuous parameter. In an exemplary application, we use this to guide the generative process to create a 3D object with a custom-fit shape. We formulate this generation process in a multi-task setting by using the concept of auxiliary classifier GANs. Further, we propose to sample the generator label input for training from a kernel density estimation (KDE) of the dataset. Our ablations show that this leads to significant performance increase in regions with few samples. Extensive quantitative and qualitative experiments show that we gain explicit control over the object dimensions while maintaining good generation quality and diversity.}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2021
- IEEE IV
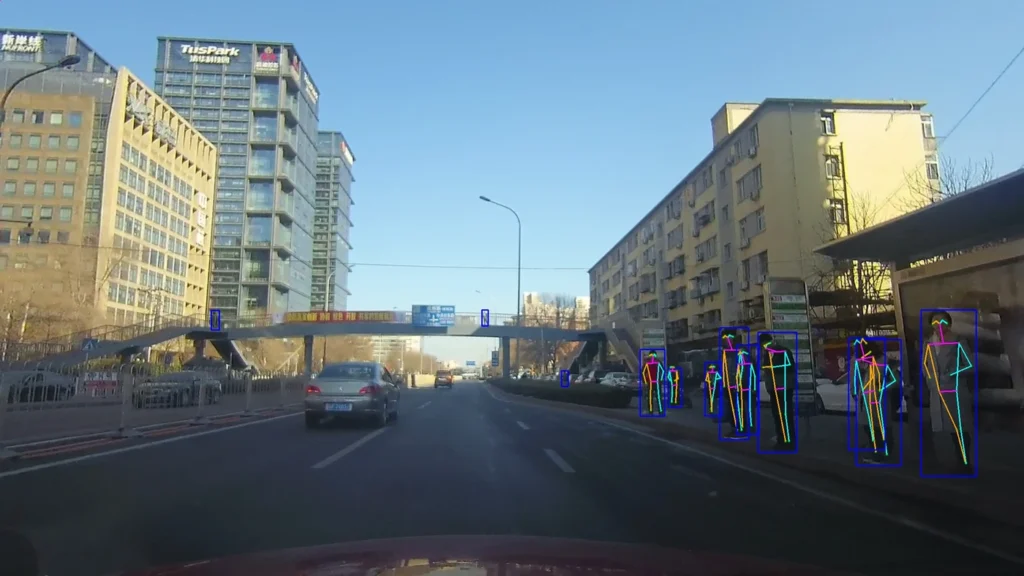
UrbanPose: A New Benchmark for VRU Pose Estimation in Urban Traffic Scenes
vulnerable road userspedestrianscyclistsbenchmarkdataset@inproceedings{Wang2021UrbanPose, title = {UrbanPose: A New Benchmark for VRU Pose Estimation in Urban Traffic Scenes}, author = {Sijia Wang and Diange Yang and Baofeng Wang and Zijie Guo and Rishabh Kumar Verma and Jayanth Ramesh and Christoph Weinrich and Ulrich Kressel and Fabian Berthold Flohr}, year = {2021}, date = {2021-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium Proceedings}, pages = {1537--1544}, organization = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE IV
Pose-Guided Person Image Synthesis for Data Augmentation in Pedestrian Detection
pedestriansdetectiongenerative modelsdatasetdata augmentation@inproceedings{Zhi2021PoseGuidedPe, title = {Pose-Guided Person Image Synthesis for Data Augmentation in Pedestrian Detection}, author = {Rong Zhi and Zijie Guo and Wuqiang Zhang and Baofeng Wang and Vitali Kaiser and Julian Wiederer and Fabian B Flohr}, year = {2021}, date = {2021-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, pages = {1493--1500}, organization = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - Conference paper
VRU Pose-SSD: Multiperson Pose Estimation For Automated Driving
vulnerable road userspedestriansdetectionbenchmarkpose estimation@inproceedings{Kumar2021VRUPoseSSD, title = {VRU Pose-SSD: Multiperson Pose Estimation For Automated Driving}, author = {Chandan Kumar and Jayanth Ramesh and Bodhisattwa Chakraborty and Renjith Raman and Christoph Weinrich and Anurag Mundhada and Arjun Jain and Fabian B Flohr}, year = {2021}, date = {2021-01-01}, booktitle = {Proceedings of the AAAI Conference on Artificial Intelligence}, volume = {35}, number = {17}, pages = {15331--15338}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE IV
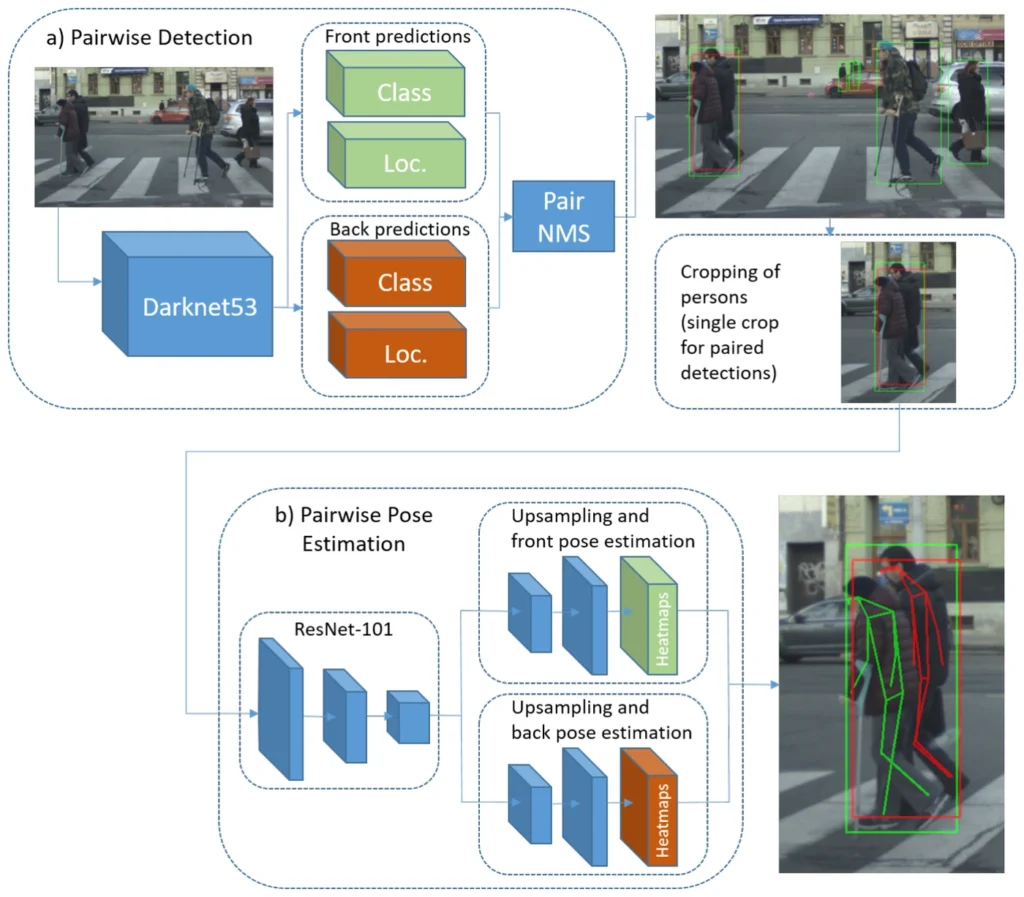
Simple Pair Pose-Pairwise Human Pose Estimation in Dense Urban Traffic Scenes
pedestriansvulnerable road usersdatasetbenchmarkpose estimation@inproceedings{Braun2021SimplePairPo, title = {Simple Pair Pose-Pairwise Human Pose Estimation in Dense Urban Traffic Scenes}, author = {Markus Braun and Fabian Berthold Flohr and Sebastian Krebs and Ulrich Kressel and Dariu M Gavrila}, year = {2021}, date = {2021-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, pages = {1545--1552}, organization = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2020
- IEEE IV
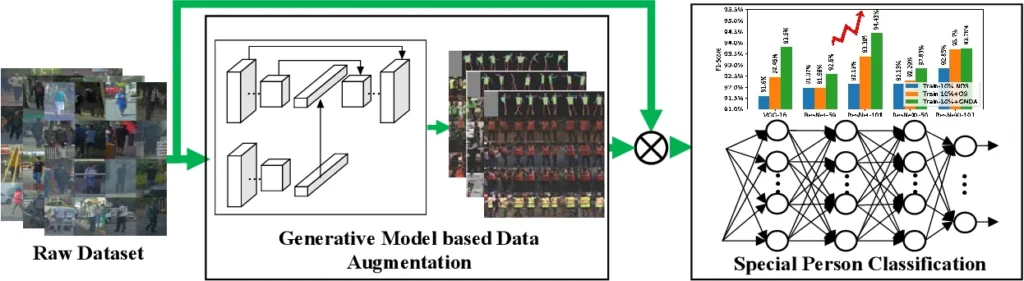
Generative Model Based Data Augmentation for Special Person Classification
pedestriansgenerative modelsdetectiondata augmentationclassification@inproceedings{Guo2020GenerativeMo, title = {Generative Model Based Data Augmentation for Special Person Classification}, author = {Zijie Guo and Rong Zhi and Wuqiang Zhang and Baofeng Wang and Zhijie Fang and Vitali Kaiser and Julian Wiederer and Fabian B Flohr}, year = {2020}, date = {2020-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE IV
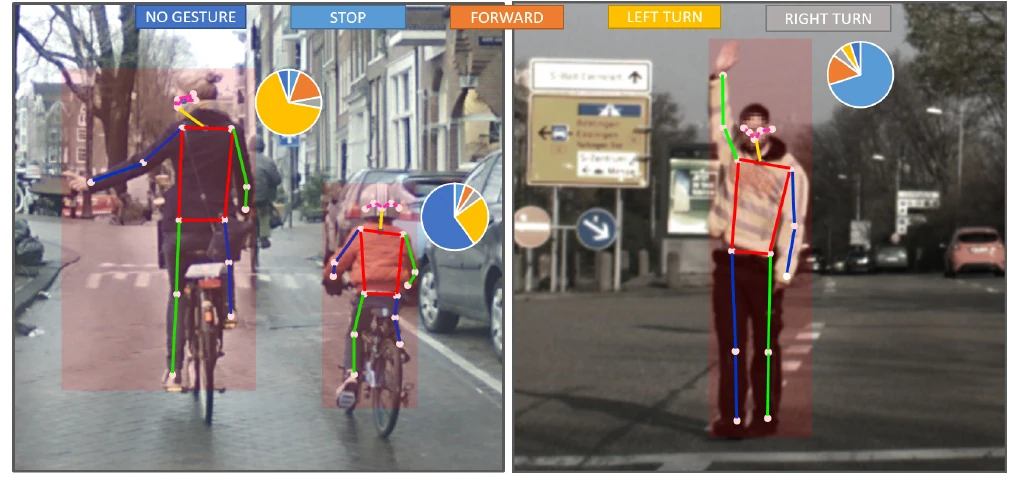
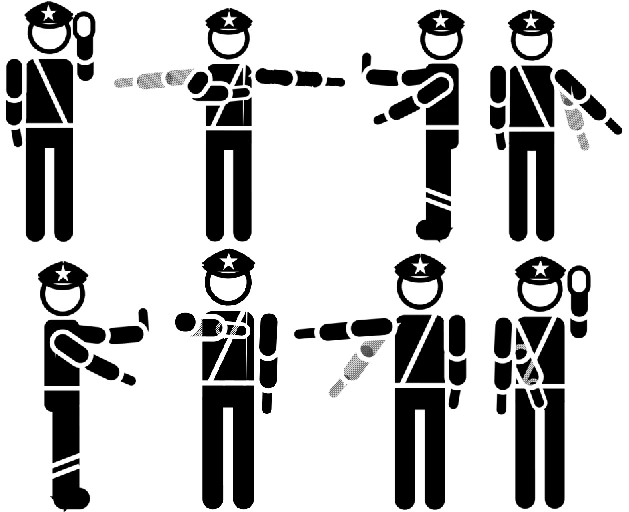
Traffic Police Gesture Recognition by Pose Graph Convolutional Networks
pedestriansintentdatasetgesture recognitiongraph neural networks@inproceedings{Fang2020TrafficPolic, title = {Traffic Police Gesture Recognition by Pose Graph Convolutional Networks}, author = {Zhijie Fang and Wuqiang Zhang and Zijie Guo and Rong Zhi and Baofeng Wang and Fabian B Flohr}, year = {2020}, date = {2020-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2019
- IJCV
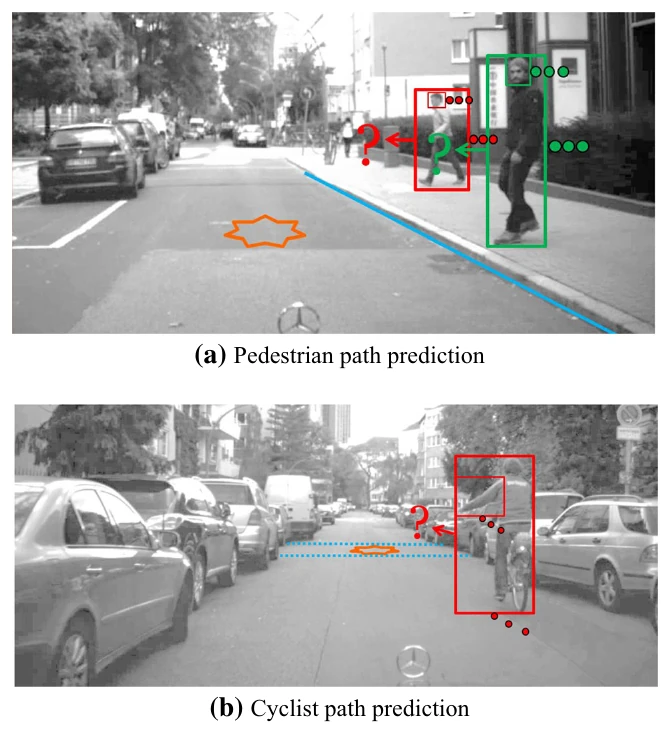
Context-based path prediction for targets with switching dynamics
pedestrianscyclistsvulnerable road userstrajectory predictionintent@article{Kooij2019Contextbased, title = {Context-based path prediction for targets with switching dynamics}, author = {Julian F P Kooij and Fabian B Flohr and Ewoud A I Pool and Dariu M Gavrila}, year = {2019}, date = {2019-01-01}, journal = {International Journal of Computer Vision (IJCV)}, volume = {127}, number = {3}, pages = {239--262}, publisher = {Springer}, keywords = {}, pubstate = {published}, tppubtype = {article} } - IEEE IV
Recurrent Neural Network Architectures for Vulnerable Road User Trajectory Prediction
vulnerable road userstrajectory predictioncyclistspedestriansbenchmark@inproceedings{Xiong2019RecurrentNeu, title = {Recurrent Neural Network Architectures for Vulnerable Road User Trajectory Prediction}, author = {Hui Xiong and Fabian B Flohr and Sijia Wang and Baofeng Wang and Jianqiang Wang and Keqiang Li}, year = {2019}, date = {2019-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, pages = {171--178}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE TPAMI
EuroCity persons: A novel benchmark for person detection in traffic scenes
pedestrianscyclistsdetectionbenchmarkdataset@article{Braun2019EuroCitypers, title = {EuroCity persons: A novel benchmark for person detection in traffic scenes}, author = {Markus Braun and Sebastian Krebs and Fabian B Flohr and Dariu M Gavrila}, year = {2019}, date = {2019-01-01}, journal = {Pattern Analysis and Machine Intelligence (PAMI), IEEE transactions on}, volume = {41}, number = {8}, pages = {1844--1861}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {article} } - IEEE ITSC
Leverage of Limb Detection in Pose Estimation for Vulnerable Road Users
vulnerable road userscyclistspedestriansdatasetpose estimation@inproceedings{Wang2019LeverageofLi, title = {Leverage of Limb Detection in Pose Estimation for Vulnerable Road Users}, author = {Sijia Wang and Fabian B Flohr and Hui Xiong and Tuopu Wen and Baofeng Wang and Mengmeng Yang and Diange Yang}, year = {2019}, date = {2019-01-01}, booktitle = {IEEE International Conference on Intelligent Transportation Systems (ITSC)}, pages = {528--534}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2018
- UvA
Vulnerable road user detection and orientation estimation for context-aware automated driving
vulnerable road userspedestrianscyclistsdetectiontrajectory prediction@phdthesis{Flohr2018Vulnerablero, title = {Vulnerable road user detection and orientation estimation for context-aware automated driving}, author = {Fabian B Flohr}, year = {2018}, date = {2018-01-01}, publisher = {UvA-DARE}, school = {University of Amsterdam (UvA)}, keywords = {}, pubstate = {published}, tppubtype = {phdthesis} }
2017
- IEEE ITSC
A survey on leveraging deep neural networks for object tracking
surveysensor fusiondetectionobject trackingdeep learning@inproceedings{Krebs2017Asurveyonlev, title = {A survey on leveraging deep neural networks for object tracking}, author = {Sebastian Krebs and Bharanidhar Duraisamy and Fabian B Flohr}, year = {2017}, date = {2017-01-01}, booktitle = {IEEE International Conference on Intelligent Transportation Systems (ITSC)}, pages = {411--418}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - ESV
Advancing active safety towards the protection of vulnerable road users: the PROSPECT project
vulnerable road userspedestrianscyclistshmiactive safety@inproceedings{Aparicio2017Advancingact, title = {Advancing active safety towards the protection of vulnerable road users: the PROSPECT project}, author = {Andrés Aparicio and Laura Sanz and Gary Burnett and Hans Stoll and Maxim Arbitmann and Martin Kunert and Fabian B Flohr and Patrick Seiniger and Dariu M Gavrila}, year = {2017}, date = {2017-01-01}, booktitle = {International Technical Conference on the Enhanced Safety of Vehicles (ESV)}, publisher = {National Highway Traffic Safety Administration}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - ROSCon 2017
Building a computer vision research vehicle with ROS
sensor fusioncameracalibrationrosresearch vehicle@article{Fregin2017Buildingacom, title = {Building a computer vision research vehicle with ROS}, author = {Andreas Fregin and Markus Roth and Markus Braun and Sebastian Krebs and Fabian B Flohr}, year = {2017}, date = {2017-01-01}, journal = {ROSCon 2017}, volume = {21}, keywords = {}, pubstate = {published}, tppubtype = {article} }
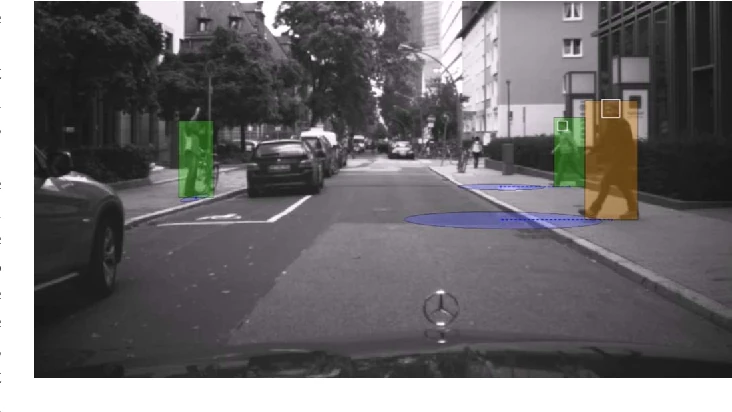
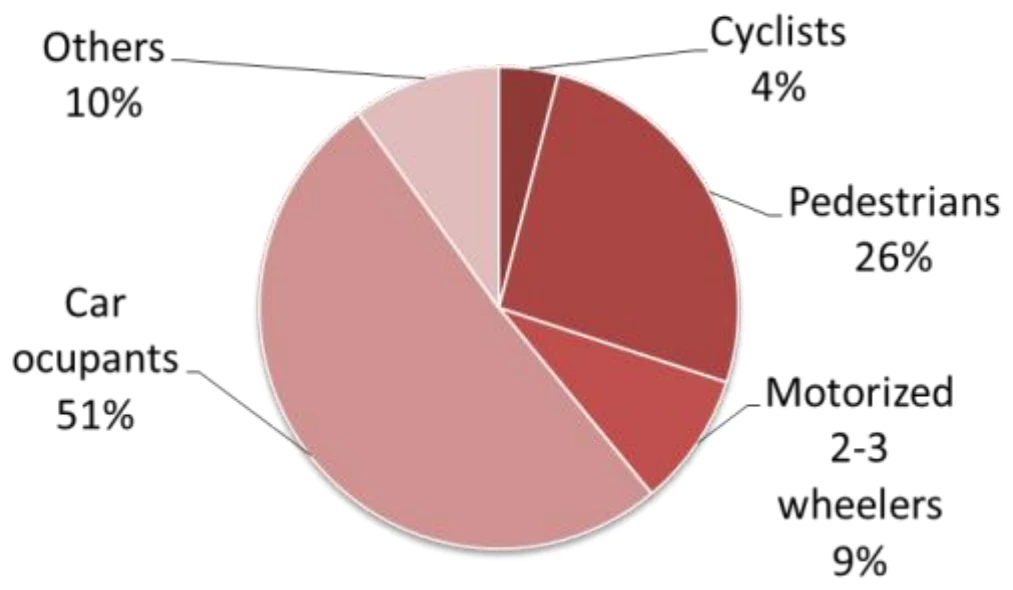
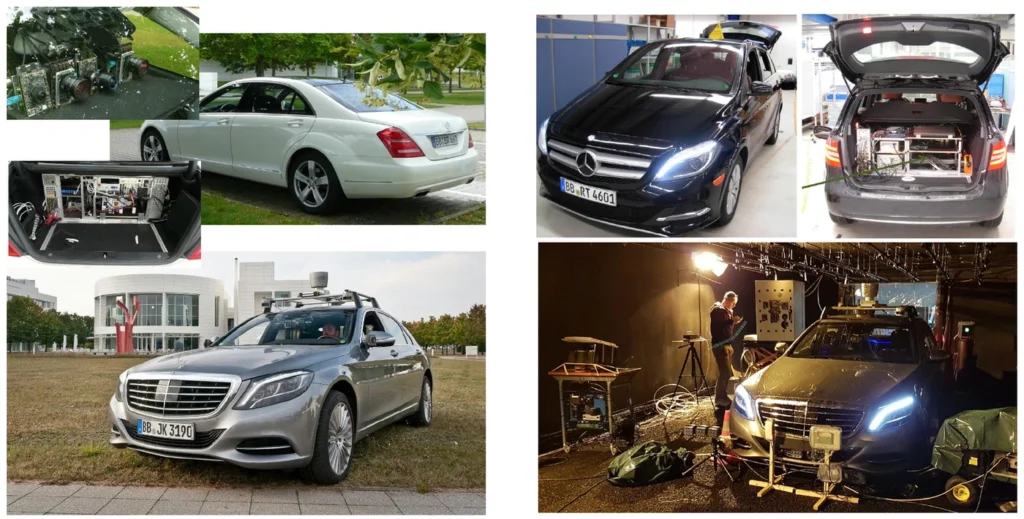
2016
- IEEE IV
Driver and pedestrian awareness-based collision risk analysis
pedestrianstrajectory predictionintentvulnerable road userscollision risk@inproceedings{Roth2016Driverandped, title = {Driver and pedestrian awareness-based collision risk analysis}, author = {Markus Roth and Fabian B Flohr and Dariu M Gavrila}, year = {2016}, date = {2016-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, pages = {454--459}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE T-ITS
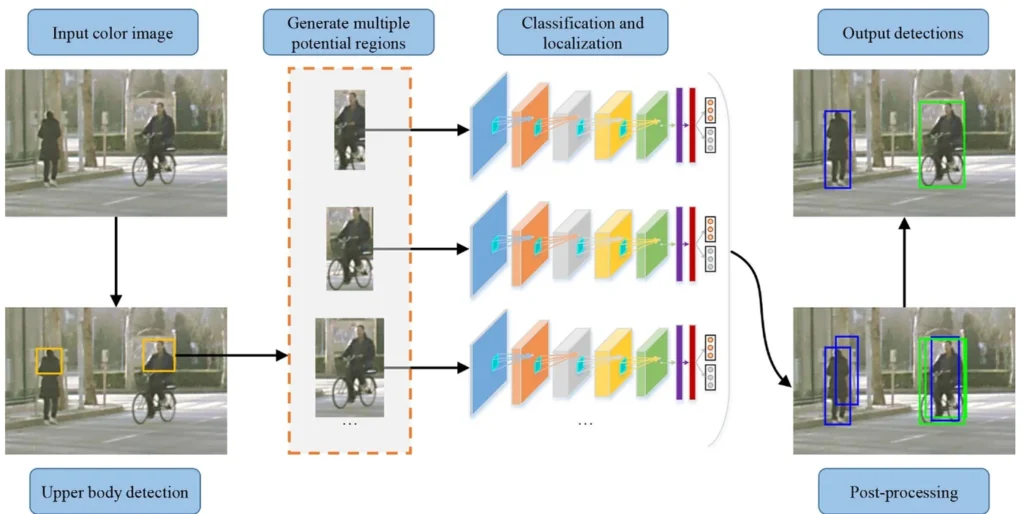
A unified framework for concurrent pedestrian and cyclist detection
pedestrianscyclistsdetectionvulnerable road usersdataset@article{Li2016Aunifiedfram, title = {A unified framework for concurrent pedestrian and cyclist detection}, author = {Xiaofei Li and Lingxi Li and Fabian B Flohr and Jianqiang Wang and Hui Xiong and Morys Bernhard and Shuyue Pan and Dariu M Gavrila and Keqiang Li}, year = {2016}, date = {2016-01-01}, journal = {Intelligent Transportation Systems (ITS), IEEE Transactions on}, volume = {18}, number = {2}, pages = {269--281}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {article} } - IEEE ITSC
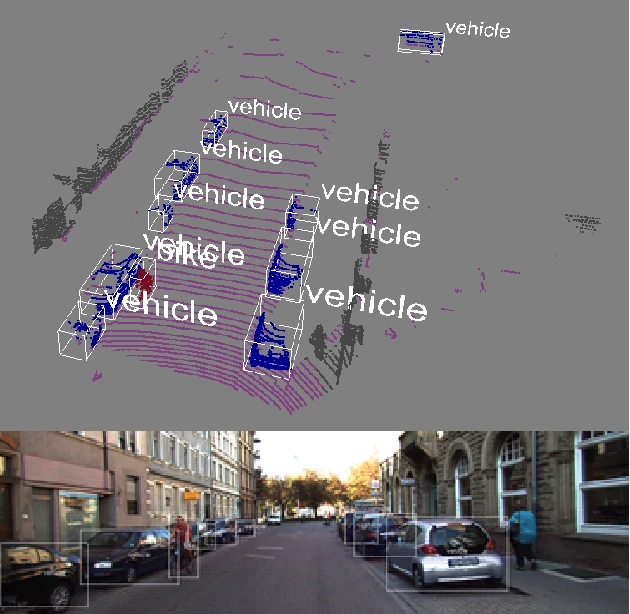
Pose-rcnn: Joint object detection and pose estimation using 3d object proposals
detection3d posecyclistslidarcamera@inproceedings{Braun2016Posercnn, title = {Pose-rcnn: Joint object detection and pose estimation using 3d object proposals}, author = {Markus Braun and Qing Rao and Yikang Wang and Fabian B Flohr}, year = {2016}, date = {2016-01-01}, booktitle = {IEEE International Conference on Intelligent Transportation Systems (ITSC)}, pages = {1546--1551}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - IEEE IV
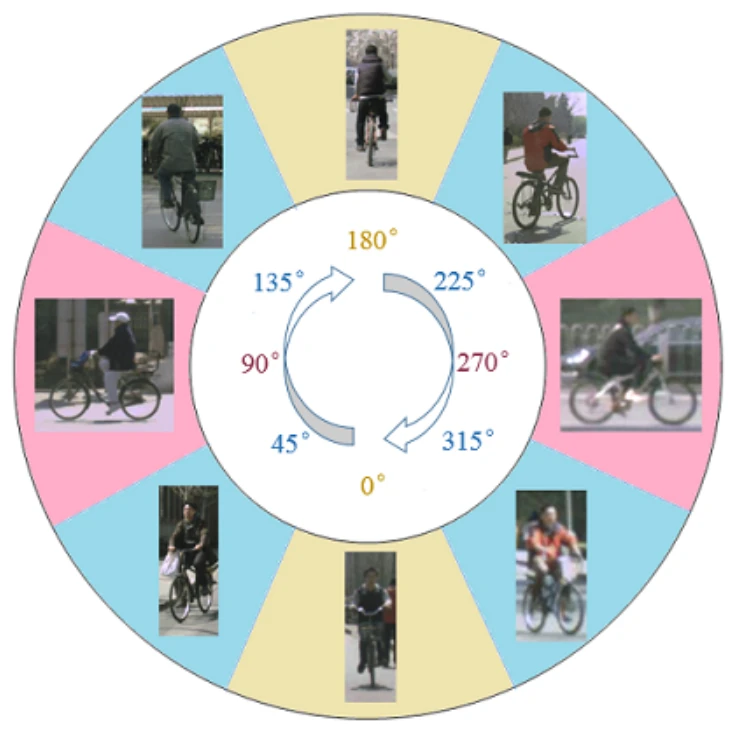
A new benchmark for vision-based cyclist detection
cyclistsvulnerable road usersdetectionbenchmarkdataset@inproceedings{Li2016Anewbenchmar, title = {A new benchmark for vision-based cyclist detection}, author = {Xiaofei Li and Fabian B Flohr and Yue Yang and Hui Xiong and Markus Braun and Shuyue Pan and Keqiang Li and Dariu M Gavrila}, year = {2016}, date = {2016-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium (IV)}, pages = {1028--1033}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
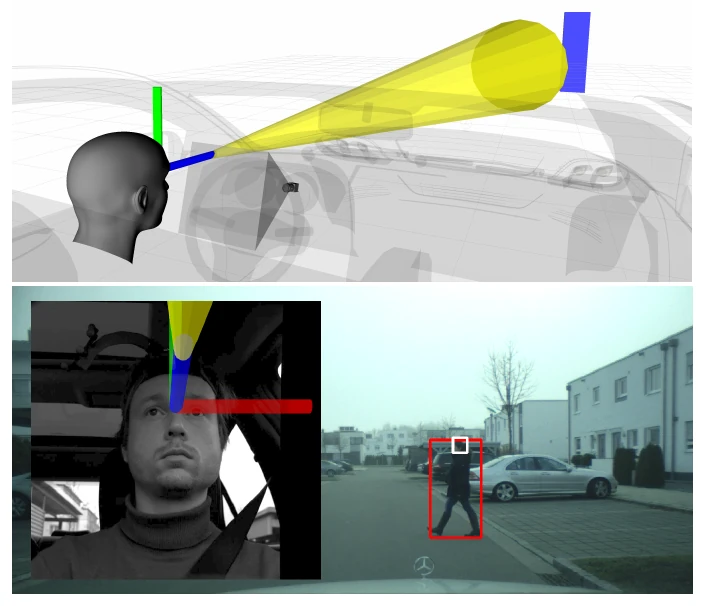
2015
- IEEE T-ITS
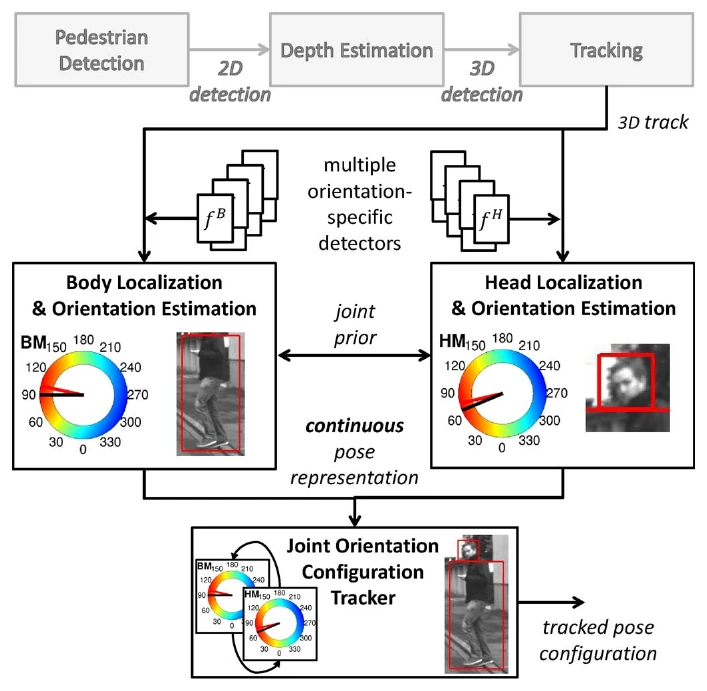
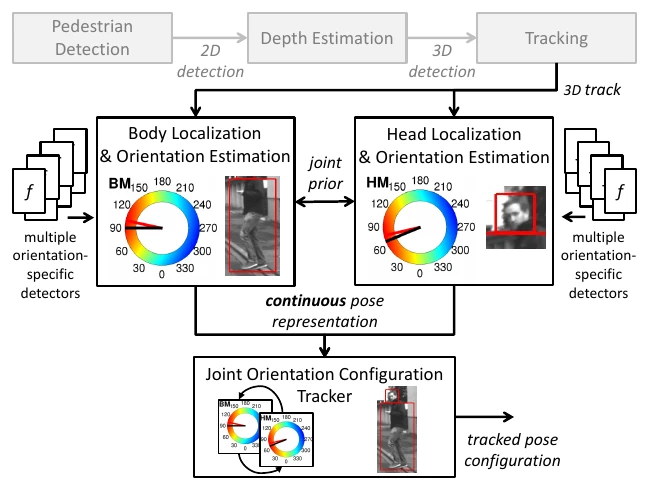
A probabilistic framework for joint pedestrian head and body orientation estimation
pedestrians3d poseintentcamerahead orientation@article{Flohr2015Aprobabilist, title = {A probabilistic framework for joint pedestrian head and body orientation estimation}, author = {Fabian B Flohr and Madalin Dumitru-Guzu and Julian F P Kooij and Dariu M Gavrila}, year = {2015}, date = {2015-01-01}, journal = {Intelligent Transportation Systems (ITS), IEEE Transactions on}, volume = {16}, number = {4}, pages = {1872--1882}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {article} }
2014
- IEEE IV
Joint probabilistic pedestrian head and body orientation estimation
pedestrians3d poseintentcamerahead orientation@inproceedings{Flohr2014Jointprobabi, title = {Joint probabilistic pedestrian head and body orientation estimation}, author = {Fabian B Flohr and Madalin Dumitru-Guzu and Julian F P Kooij and Dariu M Gavrila}, year = {2014}, date = {2014-01-01}, booktitle = {IEEE Intelligent Vehicles Symposium Proceedings (IV)}, pages = {617--622}, publisher = {IEEE}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} } - ECCV
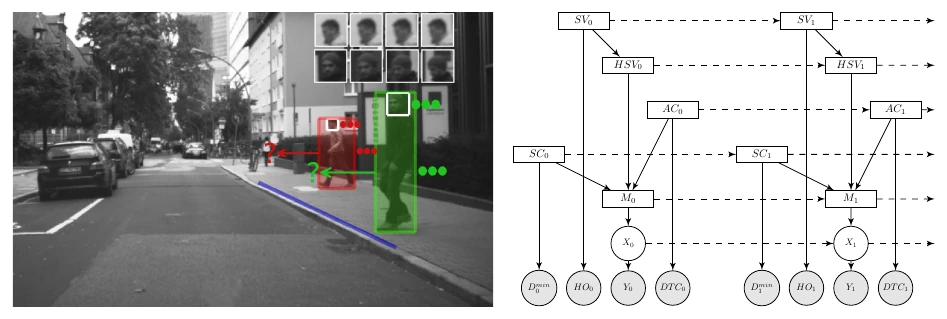
Context-based pedestrian path prediction
pedestrianstrajectory predictionintentvulnerable road usersdataset@inproceedings{Kooij2014Contextbased, title = {Context-based pedestrian path prediction}, author = {Julian F P Kooij and Nicolas Schneider and Fabian B Flohr and Dariu M Gavrila}, year = {2014}, date = {2014-01-01}, booktitle = {European Conference on Computer Vision (ECCV)}, pages = {618--633}, publisher = {Springer}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2013
- BMVC
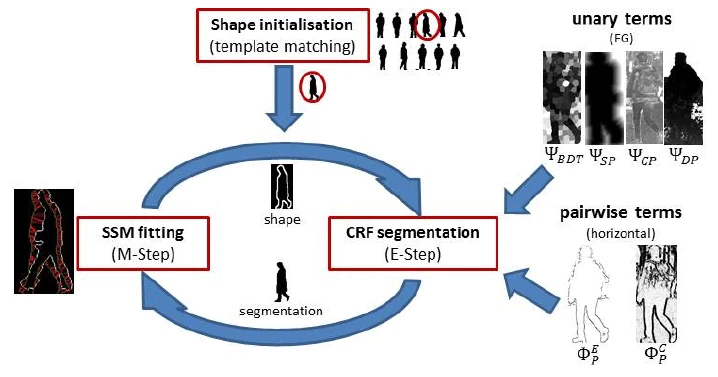
PedCut: an iterative framework for pedestrian segmentation combining shape models and multiple data cues
pedestriansdatasetbenchmarkcamerasegmentation@inproceedings{Flohr2013PedCut, title = {PedCut: an iterative framework for pedestrian segmentation combining shape models and multiple data cues}, author = {Fabian B Flohr and Dariu M Gavrila}, year = {2013}, date = {2013-01-01}, booktitle = {British Machine Vision Conference (BMVC)}, publisher = {BMVA}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
2012
- Conference paper
Evaluation of tracking methods for maritime surveillance
sensor fusionsimulationmulti-target trackingmaritime surveillance@inproceedings{Fischer2012Evaluationof, title = {Evaluation of tracking methods for maritime surveillance}, author = {Yvonne Fischer and Marcus Baum and Fabian B Flohr and Uwe D Hanebeck and Jürgen Beyerer}, year = {2012}, date = {2012-01-01}, booktitle = {SPIE Defense, Security, and Sensing}, pages = {839208--839208}, publisher = {International Society for Optics and Photonics}, keywords = {}, pubstate = {published}, tppubtype = {inproceedings} }
Lab members are set in bold. Figures are taken from the papers. All entries as one BibTeX file.