VRU Pose-SSD: Multiperson Pose Estimation For Automated Driving
Abstract
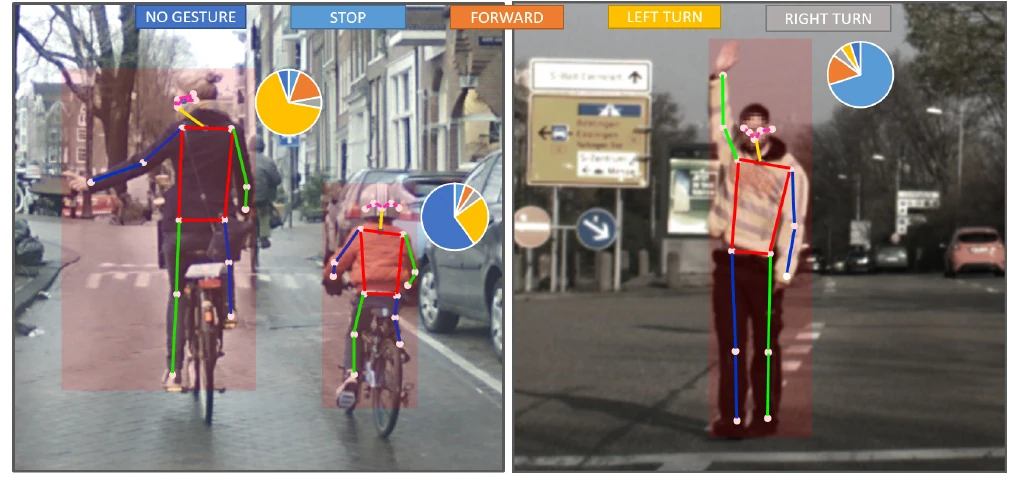
We present a fast and efficient approach for joint person detection and pose estimation optimized for automated driving (AD) in urban scenarios. We use a multitask weight sharing architecture to jointly train detection and pose estimation. This modular architecture allows us to accommodate different downstream tasks in the future. By systematic large-scale experiments on the Tsinghua-Daimler Urban Pose Dataset (TDUP), we obtain multiple models with varying accuracy-speed trade-offs. We then quantize and optimize our network for deployment and present a detailed analysis of the efficacy of the algorithm. We introduce a two-stage evaluation strategy, which is more suitable for AD and achieve a significant performance improvement in comparison to state-of-the-art approaches. Our optimized model runs at 52~fps on full HD images and still reaches a competitive performance of 32.25~LAMR. We are confident that our work serves as an enabler to tackle higher-level tasks like VRU intention estimation and gesture recognition, which rely on stable pose estimates and will play a crucial role in future AD systems.
Citation
@inproceedings{Kumar2021VRUPoseSSD,
title = {VRU Pose-SSD: Multiperson Pose Estimation For Automated Driving},
author = {Chandan Kumar and Jayanth Ramesh and Bodhisattwa Chakraborty and Renjith Raman and Christoph Weinrich and Anurag Mundhada and Arjun Jain and Fabian B Flohr},
year  = {2021},
date = {2021-01-01},
booktitle = {Proceedings of the AAAI Conference on Artificial Intelligence},
volume = {35},
number = {17},
pages = {15331--15338},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}