Speed in the blind spot: an interpretability analysis of dynamic perception in vlms for autonomous driving
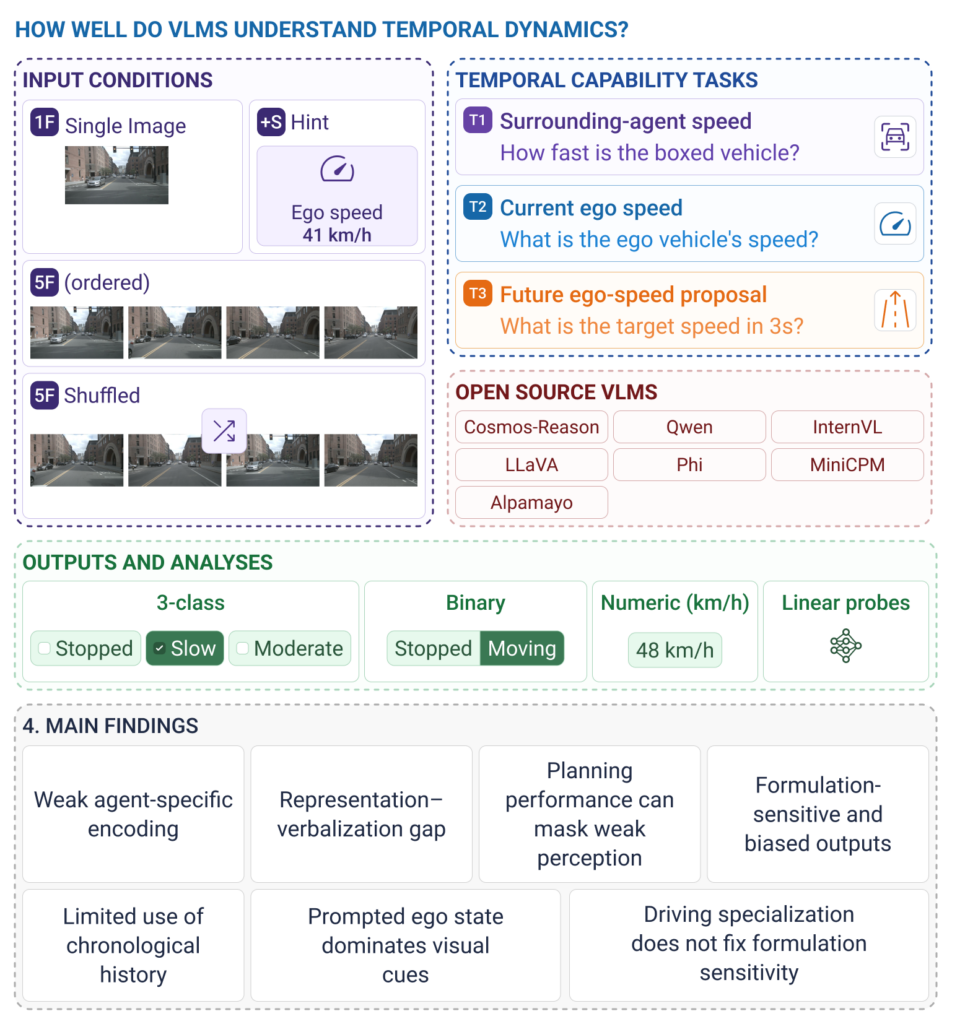
Vision-language models are increasingly used to propose what an automated vehicle should do next. Speed in the Blind Spot tests whether such proposals are grounded in the motion actually visible in the video, and finds little evidence that they are: speed is often in the model’s hidden states but not in its answer, frame order barely matters, and a prompted ego speed outweighs the pixel input.
The preprint and the evaluation & probing toolkit will be linked here as soon as they are available. Until then, feel free to get in touch (contact below).
ABSTRACT
Vision-Language Models (VLMs) are increasingly used in autonomous-driving systems, yet their ability to recover dynamic physical state from visual input remains insufficiently characterized. We study velocity understanding as a controlled diagnostic across three tasks: surrounding-agent speed, current ego speed, and short-horizon future ego-speed proposal. On nuScenes, we evaluate open-weight general-purpose and Physical-AI VLMs, together with the driving-oriented Alpamayo-1.5 Vision-Language-Action model (VLA), using multiple input and output formulations. We combine verbal evaluation with temporal perturbations, counterfactual ego-speed hints and linear probes of hidden representations. The tasks exhibit distinct failure modes. Surrounding-agent speed is weakly encoded in an agent-specific form, whereas current ego speed is often internally accessible but poorly verbalized: continuous probes achieve 4.7–5.8 km/h Mean Absolute Error (MAE) compared with 10.2–16.8 km/h MAE for verbal outputs. Multiple frames provide inconsistent verbal gains to single frame inputs, and frame order is rarely exploited. Under non-optimized Quantized Low-Rank Adaptation (QLoRA), task-specific adaptation improves both task-relevant latent speed representations and verbal readout, but continuous surrounding-agent speed estimation remains weak, while most future-speed gains survive frame shuffling, indicating limited temporal grounding. Driving specialized Alpamayo-1.5 shows stronger latent representations for surrounding-agent and future ego speed, while current ego-speed decodability is comparable and substantial probe–verbal gaps remain. Thus, driving specialization can strengthen motion representations but does not guarantee stronger encoding across both scene and ego states or reliable readout. The results show that plausible planning outputs do not necessarily imply reliable recovery or temporal grounding of the underlying dynamic state.
Citation
@inproceedings{speed-in-the-blind-spot,
  title     = {Speed in the Blind Spot: An Interpretability Analysis of Dynamic Perception in VLMs for Autonomous Driving},
  author    = {Katharina Winter, Stefan Englmeier, Fabian B. Flohr},
  booktitle = {},
  year      = {}
}