BEV-LLM
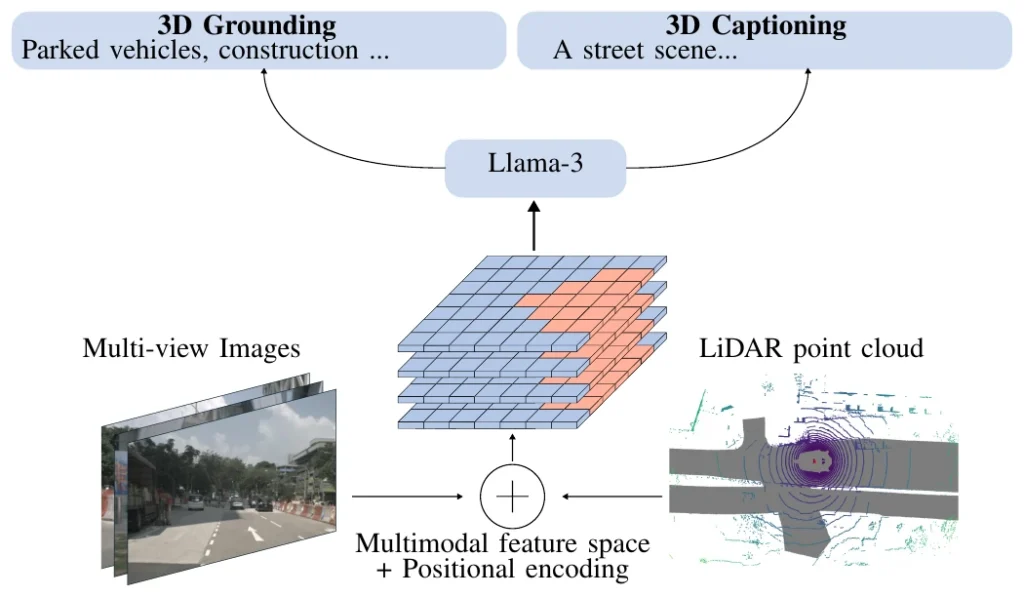
Describing a driving scene in words — who is where, who matters, what the vehicle should watch — from fused BEV and camera features.
What it does
A caption is a cheap, readable probe of what a driving model has actually understood. If the description misses the cyclist, the planner probably did too.
Abstract
Autonomous driving technology has the potential to transform transportation, but its wide adoption depends on the development of interpretable and transparent decision-making systems. Scene captioning, which generates natural language descriptions of the driving environment, plays a crucial role in enhancing transparency, safety, and human-AI interaction. We introduce BEV-LLM, a lightweight model for 3D captioning of autonomous driving scenes. BEV-LLM leverages BEVFusion to combine 3D LiDAR point clouds and multi-view images, incorporating a novel absolute positional encoding for view-specific scene descriptions. Despite using a small 1B parameter base model, BEV-LLM achieves competitive performance on the nuCaption dataset, surpassing state-of-the-art by up to 5% in BLEU scores. Additionally, we release two new datasets – nuView (focused on environmental conditions and viewpoints) and GroundView (focused on object grounding) – to better assess scene captioning across diverse driving scenarios and address gaps in current benchmarks, along with initial benchmarking results demonstrating their effectiveness.
Result
Citation
@inproceedings{Brandsttter2025BEVLLM,
title = {BEV-LLM: Leveraging Multimodal BEV Maps for Scene Captioning in Autonomous Driving},
author = {Felix Brandstätter and Erik Schütz and Katharina Winter and Fabian B. Flohr},
url = {https://ieeexplore.ieee.org/abstract/document/11097781},
doi = {10.1109/IV64158.2025.11097781},
isbn = {979-8-3315-3803-3},
year  = {2025},
date = {2025-08-06},
booktitle = {2025 IEEE Intelligent Vehicles Symposium (IV)},
pages = {345-350},
publisher = {IEEE},
abstract = {Autonomous driving technology has the potential to transform transportation, but its wide adoption depends on the development of interpretable and transparent decision-making systems. Scene captioning, which generates natural language descriptions of the driving environment, plays a crucial role in enhancing transparency, safety, and human-AI interaction. We introduce BEV-LLM, a lightweight model for 3D captioning of autonomous driving scenes. BEV-LLM leverages BEVFusion to combine 3D LiDAR point clouds and multi-view images, incorporating a novel absolute positional encoding for view-specific scene descriptions. Despite using a small 1B parameter base model, BEV-LLM achieves competitive performance on the nuCaption dataset, surpassing state-of-the-art by up to 5% in BLEU scores. Additionally, we release two new datasets — nu-View (focused on environmental conditions and viewpoints) and GroundView (focused on object grounding) — to better assess scene captioning across diverse driving scenarios and address gaps in current benchmarks, along with initial benchmarking results demonstrating their effectiveness.},
howpublished = {IEEE},
keywords = {},
pubstate = {published},
tppubtype = {inproceedings}
}